NVIDIA released CUDA 13.4, adding hardware-transparent memory boundary enforcement for GPU sharing. Paired with the new open-source GPU Fractioning Operator and KAI Scheduler v0.18.0, teams can now define specific memory requests, burst limits, and compute modes directly in Kubernetes Pod annotations.
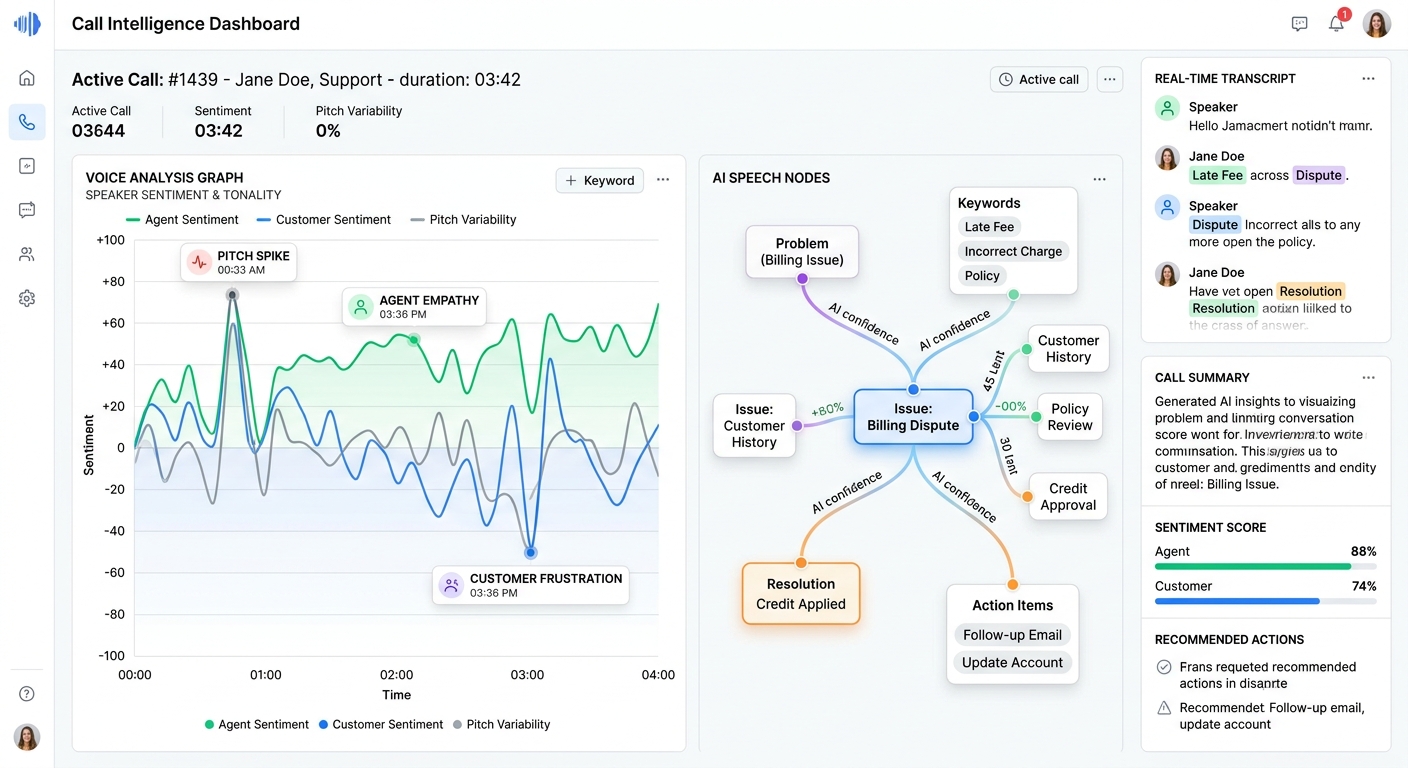
Analytics platform has been launched — a platform that transcribes every phone call, scores it against your company’s own quality criteria and turns the results into agent KPIs and coaching. It connects to 3CX, Asterisk, XCALLY, Genesys Cloud, Avaya and Cisco phone systems and works with Lithuanian, Latvian and English calls.
Mitsubishi Electric has released security updates to address multiple vulnerabilities across several industrial automation products, including GENESIS64 and the ICONICS Suite. These flaws could allow attackers to execute arbitrary code, bypass authentication, or cause denial-of-service conditions.
Google Project Zero analyzed how LLM-based systems (BigSleep) compare to traditional generative fuzzers (Fuzzilli) in finding V8 JavaScript engine vulnerabilities. Over six months, both methods independently discovered unique bugs, with an estimated overlap of approximately 25-60%.
LiquidAI has launched LFM3, a new generation of small foundation models built on a shared 2B-parameter backbone. The series includes text, vision, audio, and omni models designed for high-efficiency on-device deployment.
NVIDIA has released 'Nemotron-Personas' datasets for France and Belgium, designed to improve LLM accuracy regarding regional procedures, demographics, and cultural nuances. The update provides a complete post-training workflow—including data generation, LoRA fine-tuning via NVIDIA NeMo, and evaluation—to help developers transition from generic models to domain-specific agents.
Google DeepMind introduced Genie 4, a multimodal world model that enables real-time interactive simulations. It natively generates video, ambient audio, and responsive dialogue, utilizing Gemini 3.8 Flash to maintain physical consistency and handle multi-step reasoning.
NVIDIA has documented a threefold optimization approach to accelerate MoE inference, tested on the 124-billion-parameter Ling-3.0-flash model. By utilizing specialized Humming kernels, FP8 precision for the LM head, and Multi-Token Prediction, developers can achieve a 42.5% throughput increase and a 24.5% reduction in latency.
Google has updated its A2UI generative UI protocol to include swappable inference formats, addressing latency and reliability issues found in the previous Direct JSON approach. A new format, A2UI Express, reduces token usage by up to 3x and latency by up to 3x by using a concise Python-like syntax.
Google has launched Gemini Robotics Embodied Reasoning 2 (ER 2) in public preview on the Gemini platform. This model acts as a high-level cognitive layer for robotics, capable of planning, self-correcting tasks, and managing multi-robot systems via natural language instructions.
NIST has published NISTIR 8547, a definitive guide for migrating to quantum-resistant standards. The report addresses the urgent need to protect data against 'harvest now, decrypt later' attacks, aligning with federal mandates for high-impact systems.
n8n 3.0 has entered beta, focusing on core architectural stability, stricter security defaults, and the removal of legacy features. The transition to a container-only model for self-hosting is now mandatory, and users must use the built-in Migration Report to handle breaking changes before the stable release in December.
Researchers have developed TraceQuery, a sparse decoding framework that reduces the computational cost of diffusion large language models (dLLMs). By analyzing denoising trajectories, the method selectively recomputes only necessary token representations rather than performing redundant operations, maintaining high accuracy with fewer computations.
Researchers have introduced the Boa Compressor, an online tool utilizing a Mamba state-space model to compress long-form context into shorter representations in linear time. By distilling knowledge from full-context LLM interactions, this method allows for efficient per-query inference without the massive latency overhead of transformer-based compression.
Researchers have proposed an embedding-based k-center approach to select smaller, highly representative subsets of training data for Whisper fine-tuning. This method outperforms random sampling by capturing greater linguistic diversity, particularly effective when training budgets are limited.
Researchers introduced Recursive Semantic Divergence (RSD), an unsupervised metric that measures and penalizes inconsistency in LLM agent trajectories. By applying RSD as a reward signal during fine-tuning, models exhibit significantly more stable behavior and higher success rates across tool-use benchmarks.
CISA has officially designated two PHP flaws, CVE-2026-109618 and CVE-2026-109619, as actively exploited in the wild. You should prioritize these for immediate remediation to prevent potential system compromise.
Cloudflare identified a security flaw in the SGLang inference engine that caused cross-request data exposure for the GLM-5.3 model. Requests exceeding the configured KV cache pool size were incorrectly handled, causing the decode node to generate responses using stale KV cache pages belonging to other users.
Apple has unveiled GHARP, a new method for animating 3D human heads in real time using a two-stage Gaussian Splatting approach. By separating static identity reconstruction from lightweight, mobile-optimized expression prediction, the model achieves state-of-the-art results on the Ava-256 benchmark while remaining computationally efficient.
Google has introduced Gemini Omni, a new video-generation model capable of creating and editing clips from text and image prompts. The model is now the default for Google's video workflows, while the previous Veo model has been deprecated in the API.
OpenAI has officially released GPT-6.1 Terra, a new model specifically engineered to excel in visual reasoning, precise computer navigation, and natural language generation.
Amazon Bedrock now supports explicit and implicit prompt caching for OpenAI models, allowing you to store and reuse static prompt prefixes like tools, instructions, and conversation history. By avoiding the re-processing of identical tokens across turns, you can significantly lower input costs and improve responsiveness in complex agent workflows.
Google Cloud has released IAM Helper, a suite of agent-facing building blocks designed to automate complex Identity and Access Management (IAM) workflows. By integrating with Google Cloud's core IAM engines via MCP (Model Context Protocol), these tools enable autonomous agents to handle tasks like troubleshooting 403 errors, simulating policy impacts, and requesting just-in-time access.
NVIDIA has expanded its Mission Control platform to include autonomous recovery for Kubernetes environments managed by Run:ai. The system now separates job-level recovery from hardware-level maintenance, allowing training tasks to restart on healthy nodes while simultaneously diagnosing faulty infrastructure.